

Demonstrating network redundancy means being able to prove with concrete documentation, test results, and reports that your network automatically continues to operate during a failure without data loss or prolonged downtime. This is not only relevant for internal quality assurance, but also for audits, compliance processes, and accountability to management or regulators. In this article, we answer the most frequently asked questions about proof, testing, documentation, and reporting of network redundancy.
What counts as proof of network redundancy?
Proof of network redundancy consists of a combination of technical configuration documentation, test results, and monitoring logs that together demonstrate that a functioning alternative path or system is genuinely available in the event of a failure. A single document is never sufficient. It is about the totality of design, verification, and operational data.
In practice, valid proof consists of the following elements:
- Network topology diagrams showing redundant paths, failover routes, and backup connections
- Configuration exports from switches, routers, and firewalls showing how redundancy is configured (such as LACP, RSTP, OSPF, or BGP multi-path)
- Failover test results with timestamps demonstrating how quickly the network switches over during a simulated failure
- Uptime reports and SLA data over an extended period
- Monitoring data that continuously tracks the availability of primary and secondary connections
Important: proof is only valid if it is current. A diagram from 2023 proves nothing about the situation in 2026 if infrastructure changes have been made since then. Ensure version control and date every document.
How do you test whether redundancy actually works?
You test network redundancy by deliberately simulating a failure and measuring whether the network automatically switches to the alternative path within the defined recovery time, without critical services going down. Testing is the only way to prove that redundancy not only exists on paper, but also works in practice.
An effective testing method follows these steps:
- Define the test scenario: Which component fails? An uplink, a switch, a fiber connection, a router? Document the scenario in advance.
- Establish measurement criteria: What is the maximum acceptable failover time? What must not be interrupted?
- Perform the test during a maintenance window: Physically or logically disconnect a component and measure the impact.
- Record the results: Note the exact timestamps of the failure, switchover, and recovery. Use monitoring tools that provide real-time insight.
- Repeat periodically: A one-time test is insufficient. Annual or semi-annual tests are the standard for critical infrastructure.
Also pay attention to testing partial failures. Complete outage is not the only risk. Degradation of a connection, packet loss, or latency spikes can be just as damaging to business-critical processes. Real-time fiber monitoring helps to immediately detect and document these kinds of subtle anomalies.
What documents are required for a redundancy audit?
For a redundancy audit you need at minimum a current network design, configuration documentation, test reports, a change log, and monitoring reports. Together these documents form the demonstrable proof that redundancy is structurally embedded in the network infrastructure, not present by coincidence.
The complete documentation set for an audit includes:
- As-built network topology: A current diagram of the physical and logical infrastructure, including all redundant connections and failover paths
- Configuration documentation: Exports or screenshots of relevant network configurations, including redundancy protocols such as STP, VRRP, or BGP
- Failover test reports: Dated reports of completed tests with measurement results and conclusions
- Change log: An overview of all changes to the infrastructure, demonstrating that redundancy has remained intact after changes
- SLA reports and uptime data: Historical availability data covering at least the past twelve months
- Incident reports: Documentation of any failures and how the redundancy performed during those events
- Risk analysis: An overview of single points of failure and how these have been mitigated
Auditors look not only at whether the documents exist, but also at whether they are consistent. If the diagram does not match the configuration exports, that is a finding. Ensure a management process that keeps documentation in sync with the actual infrastructure.
What is the difference between redundancy at layer 1 and layer 2?
Redundancy at layer 1 (the physical layer) means that multiple physical connections, cables, or fiber routes are present. Redundancy at layer 2 (the data link layer) means that protocols are active that automatically switch to an alternative logical path within the same network segment. Both layers are required for complete network availability.
Layer 1: physical redundancy
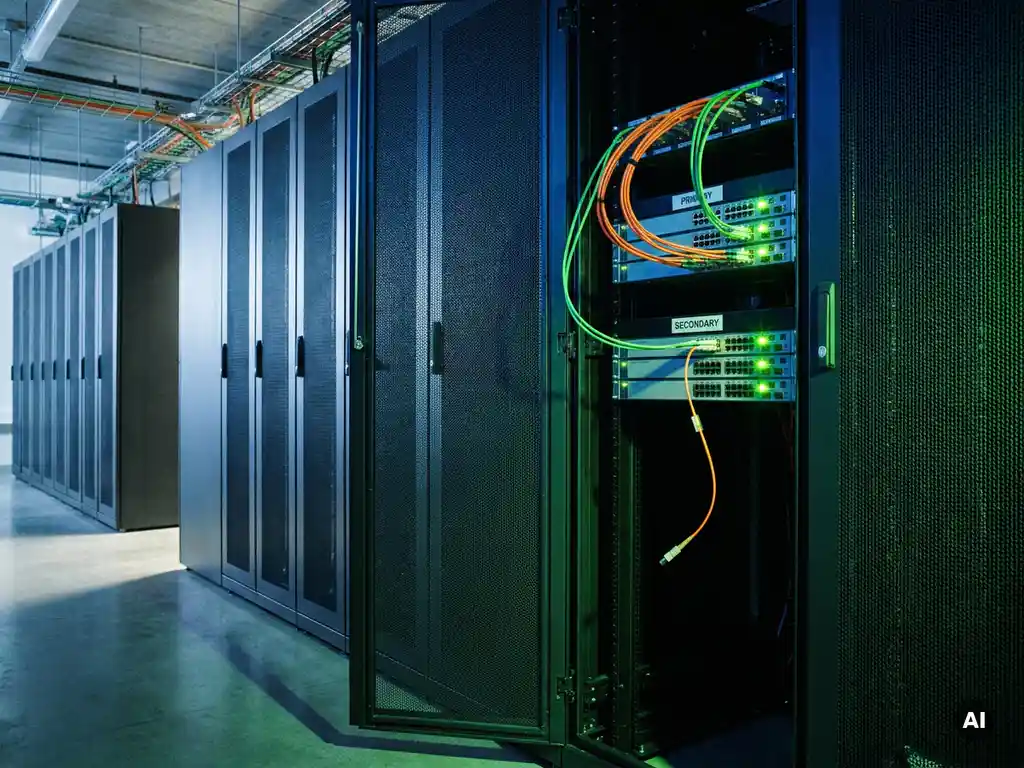
At layer 1, it is about the tangible infrastructure. Think of dual fiber connections via different physical routes, redundant power supplies for active equipment, or dual uplinks from a data center to the backbone. Layer 1 redundancy protects against physical damage, cable cuts, or the failure of a single device. Without layer 1 redundancy, every layer 2 provision is meaningless if the cable is accidentally severed.
Layer 2: logical redundancy
At layer 2, protocols such as Spanning Tree Protocol (STP), Rapid STP, or Link Aggregation Control Protocol (LACP) work to manage redundant logical paths. These protocols prevent network loops and ensure that when an active path fails, an alternative path is automatically activated. Layer 2 redundancy is invisible to end users, but essential for uninterrupted switchover.
For a demonstrably redundant network, document both layers separately. In an audit, you want to be able to show that the physical infrastructure offers multiple paths and that the logical configuration correctly manages these paths. Layer 2 redundancy alone without a layer 1 backup is vulnerable. Layer 1 redundancy alone without layer 2 management leads to network loops or inefficient use of available paths.
When is network redundancy legally required?
Network redundancy is legally required in sectors and situations where the continuity of digital services is established in legislation or regulation. In 2026, the most important frameworks in Europe are the NIS2 directive, the DORA regulation for financial institutions, and sector-specific standards such as those for healthcare and critical infrastructure.
The NIS2 directive requires organisations in essential and important sectors — including energy, transport, healthcare, drinking water, and digital infrastructure — to take measures to ensure the continuity of their network and information systems. Redundancy is an explicit requirement, although the directive does not prescribe a specific technical solution. Organisations must demonstrate that they have identified risks and taken appropriate measures.
DORA, the Digital Operational Resilience Act, goes further for financial organisations. It sets requirements for recovery capacity, testing obligations, and reporting to supervisory authorities. Network redundancy is a basic requirement within a broader ICT resilience framework.
Beyond these legal frameworks, many sectors operate with ISO 27001 certification or other standards where demonstrable network availability is part of the audit. Contractual SLA obligations to customers or partners can also effectively make redundancy mandatory, even without a direct legal basis. Our security solutions align with these compliance requirements and help make your infrastructure demonstrably compliant.
How do you report network redundancy to management or the board?
Report network redundancy to management or the board by translating technical data into business risks and outcomes. Avoid jargon, and link availability figures to concrete consequences for business continuity, revenue, and reputation. A good redundancy report shows what the current situation is, what has been tested, and what the remaining risks are.
An effective redundancy report for executives includes:
- Availability score: The measured uptime over the reporting period, expressed as a percentage and translated into hours of potential downtime
- Overview of redundant connections: Which critical connections are duplicated and which are not yet
- Test results in plain language: “During a simulated failure of the primary uplink, the network switched to the secondary path within 30 seconds, without interruption to critical applications”
- Risk overview: Which single points of failure remain and what is the planned approach
- Compliance status: The extent to which the infrastructure complies with applicable regulations such as NIS2
- Improvement points and planning: Concrete actions for the coming quarter or year
Executives make decisions based on risk and investment. Link every technical fact to a business impact. “We have no redundancy on connection X” becomes: “If connection X fails, production site Y is down for an average of four hours, with an estimated revenue loss of Z.” That makes the urgency tangible and the investment in redundancy open for discussion.
For organisations that need structured monitoring and reporting, monitoring and network management provides a solid foundation for maintaining continuous insight into the availability of critical connections and reporting this periodically to stakeholders.
Ready for the next step?
Explore our solutions or get in touch directly with one of our experts.